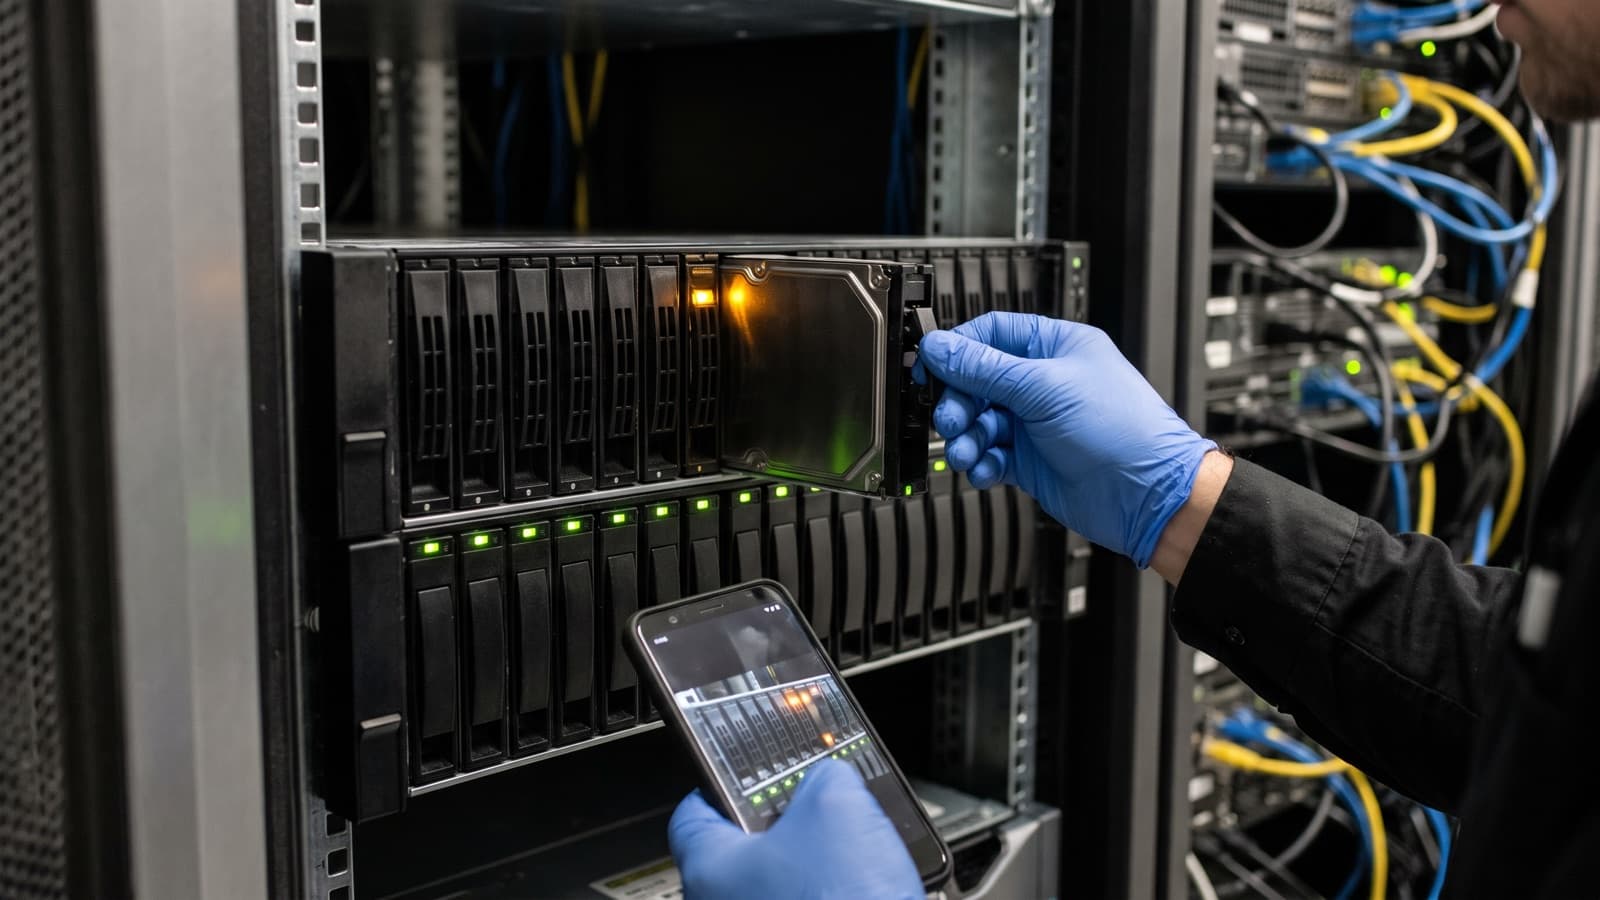
Your monitoring says a drive has failed. Your controller says which one, in software. Nobody is standing at the server. The hard part is turning a line in a log into the right piece of metal in the right bay, and doing it without making things worse.
This guide walks through how a remote hands technician does that. It covers what you prepare, how the drive is identified, what the technician must not do, the swap itself, and what happens to the old drive. It applies to servers and storage arrays alike.
What does a technician need to replace a failed drive?
A technician needs enough detail in the ticket to find the exact drive without guessing: the device, its position, the bay, the serial number and the rules for the old drive. The controller or operating system gives you most of it from your desk.
Collect these details before you raise the ticket. They match the six parts of a good remote hands ticket, applied to one task. The sample below shows how short a complete drive ticket can be.
- Device: server or array name, make and model, and the label printed on the chassis.
- Location: facility, cabinet and U position, for example cabinet 12, U20.
- Drive: bay or slot number, drive serial number from the controller or OS, and the array or volume it belongs to.
- Replacement part: where it is on site, its part number and serial number, and whether it is already in a caddy.
- Hot swap: whether the server supports it, per your vendor documentation.
- Old drive: bag and label, return to vendor under RMA, hold for sanitizing, or send for destruction.
- Confirmation: who on your side triggers the locate light and confirms the rebuild, with a phone number that answers during the visit.
What does a sample failed drive ticket look like?
A good failed drive ticket reads like a short set of instructions with a stop condition. The example below is generic, with made-up names, to show the level of detail.
- Server DB-STOR-02, cabinet 12, U20. Label on the front reads DB-STOR-02.
- Failed drive: bay 5. Serial number on the controller is the one in the attached screenshot.
- Step 1: Read the serial number on the drive in bay 5. Photograph it. Send it to me before you touch anything.
- Step 2: Wait for my confirmation. I will trigger the locate light from the management interface.
- Step 3: Remove the drive. Fit the replacement from the parts bag on the shelf at U1. Match the caddy type.
- Step 4: Photograph the new drive in place and its serial number. Call me. I will confirm the rebuild started.
- Old drive: bag it, label it with bay and server name, and hold it in the site lockbox. Do not return it yet.
- Stop and call if the serial number does not match, two bays show faults, or the replacement does not fit.
How does a technician physically find the right drive?
A technician finds the right drive by using more than one signal and by never trusting a single one. The usual signals are the bay number, the fault light, the locate light and the serial number on the drive label.
Start with the bay number. Most servers number their bays on the chassis, but the numbering can start at zero or one and can run in different directions. Your engineer should say which numbering the controller uses, or state it in the ticket.
Then use the lights. Many servers and arrays show a fault light on a failed drive, and many let your engineer trigger a locate or identify light from the controller or management interface. Colors and blink patterns vary by vendor and model, so follow the vendor documentation and do not assume a color means the same thing everywhere. One vendor FAQ notes that a blinking red light on a hot spare marks the spare and is not a failure warning.
The serial number is the final check. On many drives you can read it on the label without pulling the drive out. If it is on the back or side and the drive must come out to read it, agree that step with your engineer first. The technician photographs the label and sends it for comparison with the serial number the controller reports.
- Bay number matches the ticket.
- The fault or locate light is on the same bay.
- The serial number on the label matches the one on the controller.
- The photo of the label has been seen by your engineer, who says go.
What should a technician never do with a failed drive?
A technician should never pull a drive on a single signal, and never without a second confirmation from the customer. A wrong pull on an array that is already degraded can turn a routine replacement into data loss.
Many arrays tolerate a limited number of failed drives. Once one drive has failed, that tolerance may already be used up, and the exact amount varies by RAID level and configuration. If the wrong drive is pulled, the volume can go offline or lose data. Some systems recover when the drive is put back quickly, but do not rely on that.
- Do not pull a drive because it is the only one with a light on. Lights can be wrong or can mark a spare.
- Do not pull a drive if the serial number does not match. Stop and call.
- Do not pull a second drive to see whether it helps.
- Do not swap drives between bays to test them unless the ticket says so.
- Do not continue if two or more drives show faults. That is a different job and your engineer must decide.
- Do not leave the old drive unlabeled or loose on top of the rack.
How is the drive swapped: hot swap or power down?
Whether a drive can be swapped with the server on depends on the hardware, so the ticket should state it and the technician follows the vendor documentation. Many servers and arrays use hot-swap drives in caddies, others need the server powered down first.
Match the replacement to what the vendor and your engineer specify: size, interface type, speed and, where the vendor requires it, firmware or a certified part number. A drive that fits the bay may still be refused by the controller or run slower than the others in the array. Use the same caddy type and orientation as the drive removed. Press the latch, slide the drive out, wait for it to stop spinning if it is a spinning disk, and slide the new one in until it seats.
Take a photo of the bay before and after. It gives both of you a record of what was removed and where the new drive went.
| Case | What the technician does |
|---|---|
| Hot swap supported | Removes and replaces the drive with the system running, after the second confirmation. |
| Power down required | Waits for your approval, shuts down in the agreed order, swaps the drive, powers on and reports status. |
| Not sure | Stops and calls. Your engineer or the vendor documentation decides. |
What happens after the swap?
After the swap your engineer confirms that the controller sees the new drive and the rebuild has started. The technician is not the one to judge the array's health, because they may not have access to the controller.
The failed drive should be treated as data-bearing media until your instructions say otherwise. Failed does not mean empty, and a drive that cannot be read by you may still be readable by someone else.
NIST SP 800-88 Rev. 2, Guidelines for Media Sanitization, helps organizations choose how to sanitize and dispose of media based on how sensitive the data is. Treat it as a starting point for your own rule and follow what your security team decides. Do not ask a technician to improvise.
Chain of custody means a written trail of who held the drive and when. Bag the drive, label it with the server name, bay, serial number and date, and record who took it away. If the drive goes back under RMA, check the vendor's terms first, because some require return of the failed part and some offer other options for drives that held data.
Your instructions for the old drive usually fall into one of three choices.
- Return to the vendor under RMA. RMA stands for return merchandise authorization: the vendor gives you a reference number that lets you send back a failed part under warranty or a support contract. The terms vary by vendor, including packaging and how soon the part must come back.
- Hold for sanitizing. The drive is bagged, labeled and kept until it is wiped or destroyed under your rules.
- Send for destruction. The drive goes to a disposal route you have chosen, with a record of who took it.
What does the customer decide and what does the technician do?
The customer decides what is allowed and what counts as done, and the technician carries out the physical steps and records them. Splitting the work this way keeps decisions with the person who understands the data.
| Customer decides | Technician does |
|---|---|
| Which drive failed and which bay it is in | Reads the label and photographs it for comparison |
| When to start and whether to power down | Waits for the go, then follows the agreed method |
| Which replacement part to use | Checks the part number and type before fitting it |
| Triggers the locate light and confirms the rebuild | Confirms the light and bay on site and reports what the display shows |
| What happens to the old drive | Bags, labels and hands over the drive as instructed |
What should the visit report show?
The visit report should let you check the work without calling anyone. It records what was found, what was changed and where the old drive went.
Ask for photos of the bay and label before the swap and the new drive after it, the serial numbers of both drives, the time of each step and the name of the person who gave the second confirmation. The report also names where the old drive is and who has it. See what a visit report should contain for a fuller list.
Key takeaways
- Put the server, position, bay, serial number and old drive rule in the ticket before the visit.
- Use bay, light and serial number together, and send the label photo for confirmation before the pull.
- Never pull a drive on one signal, and stop if two bays show faults.
- Your engineer confirms the rebuild. The technician records both serial numbers.
- Treat the failed drive as data-bearing media and agree the RMA, sanitize or destroy rule up front.